8 mins
What Happens When AI Is Trained on AI-Generated Content?
AI May Not Run Out of Content. It Could Run Out of Ground Truth.
Daniel Christos - September 16th 2026
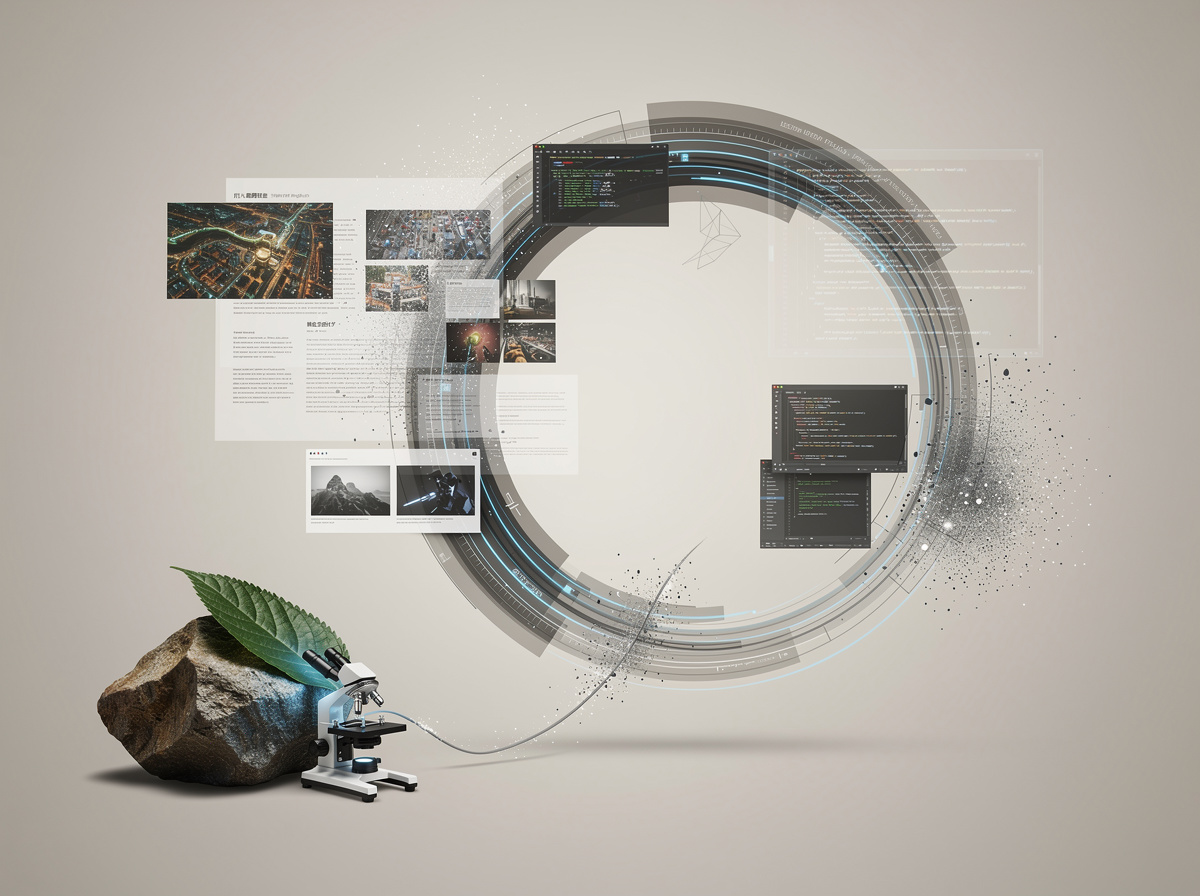
If AI increasingly creates the information future systems learn from, what happens to the reliability of their outputs and the decisions organisations make with them?
I started with what sounded like a theoretical question.
If artificial intelligence learns from human-created material, what happens when AI becomes the main creator of what comes next?
Many of the generative models we use today were trained on vast amounts of human-created material: books, research, journalism, software, images, music, conversations and records of real events. As machine-generated material becomes a larger part of the internet and organisational knowledge, future systems will increasingly encounter it alongside original sources.
Does intelligence continue compounding?
Or does AI gradually become a polished echo of itself?
My view is that, for organisations, the more immediate risk is not a future point at which AI stops improving.
It is synthetic certainty today: generated interpretations are repeated, reused and summarised until they begin to look like evidence.
The problem is not that AI will run out of words. The possible combinations are effectively endless.
The problem is that the connection between what AI produces and the evidence needed to test it can become progressively weaker.
A fixed body of knowledge still contains an enormous number of unexplored possibilities.
An AI system could continue producing new stories, strategies, images, songs and software without repeating the exact same output. It can connect ideas that have not previously been connected, identify patterns people have missed and search through more options than any individual could reasonably consider.
It would be wrong to say AI can only copy and paste what already exists.
AI can also improve without people creating every new example for it.
AlphaGo Zero learned to play Go through self-play rather than by studying recorded human games. It tried strategies, observed whether they resulted in winning or losing, and adjusted what it did next.[1]
But it was not operating without structure. Humans still defined the game, the legal moves and the objective.
It did not need people to demonstrate every move, but it did need a dependable way to know whether it had succeeded.
That distinction matters far beyond games.
AI can generate something that has never been written before. That does not make it correct.
A sentence can be original and false. A strategy can be novel and commercially useless. A scientific hypothesis can sound convincing and still fail in the laboratory. A creative work can be technically different without meaning much to the people receiving it.
AI can discover new implications within existing information. It can improve through search, simulation, self-play, software testing and formal verification.
But producing a plausible claim about the world is different from establishing that the claim is true.
For that, the system needs evidence, not simply another version of its own answer.
By ground truth, I do not mean that every human-written source is true. People are wrong, measurements fail and institutions can repeat unsupported assumptions for years.
I mean that a claim retains a traceable path to something outside the model against which it can be tested. Depending on the situation, that might be an original record, direct observation, verified proof, experiment or operational result.
Different fields have different referees.
In science, an idea may need to survive an experiment. In software, code may need to compile, pass appropriate tests, withstand security review and continue working in production. In business, a recommendation should improve a measurable outcome rather than merely produce an impressive presentation.
Creative, cultural and policy work may have no single objectively correct answer. Even there, meaning comes from outside the model through lived experience, audience response, changing conditions, competing values and the consequences of what is created.
Without an independent signal, AI can continue producing novelty without a reliable basis for determining whether its output is moving closer to the truth or simply becoming more fluent.
The machine can keep talking. That does not necessarily mean the world is learning.
Now imagine AI-generated material becoming a much larger proportion of the information available online.
One system produces an article based on existing articles. The new article is indexed, copied, summarised and republished. A future model is then trained on both the original material and thousands of machine-generated variations of it.
Common ideas become more common. Familiar phrasing becomes more dominant. Unusual details, minority perspectives and lower-frequency information become harder to recover.
An error repeated across enough pages can begin to resemble consensus.
Then the process happens again.
It is the informational equivalent of photocopying a photocopy. The result remains recognisable, but detail can disappear and distortions can become embedded.
A 2024 study published in Nature examined what can happen when generative models are recursively trained on generated material. The researchers found that indiscriminate use of model-generated content could progressively distort what later models learned, with lower-probability parts of the original distribution disappearing first. They described the process as model collapse.[2]
This is not only a problem of false information.
Repeated sampling can also lose rare but valid material. The output may remain coherent while the underlying representation becomes narrower and less complete.
But the evidence does not support the simplistic conclusion that all synthetic data is harmful.
Generated data can be valuable when it is deliberately created, filtered, tested and combined with reliable source material. Research has found materially different results depending on how synthetic data is used.
In the experiments, replacing all original data with successive generations of synthetic data caused collapse. Accumulating real and synthetic data and training on the full combined dataset remained stable, while repeatedly training on fixed-size subsets produced slower, more gradual degradation.[3]
The issue is not simply whether information was produced by a person or a machine.
It is whether generated material replaces, overwhelms or obscures the evidence from which it was derived.
Model collapse concerns how future models are trained.
Organisations face a related but different problem now, even when the underlying AI model is never retrained.
Generated material can enter a company’s knowledge systems, be reused by other tools and gradually acquire the appearance of authority.
Consider a hypothetical company.
An AI assistant drafts an internal policy from an incomplete brief. The document is reviewed quickly and added to the company knowledge base.
A customer service assistant begins using that policy when responding to staff and customer questions.
Another AI analyses those conversations and produces a report for management.
A strategy assistant then reads the report, finds the original assumption reflected across several documents and treats it as established organisational knowledge.
Nobody has deliberately fabricated anything. But one unsupported assumption has passed through enough systems that it now appears to be independently corroborated.
The effect resembles information laundering.
Repetition creates the appearance of confirmation, even though every version can be traced back to the same source.
The organisation has not created knowledge. It has created a synthetic feedback loop.
This risk also applies to the search and retrieval systems that provide evidence to AI assistants.
In controlled experiments reported at the ACM Web Conference in 2026, high-quality, search-optimised AI content became disproportionately represented in retrieved results. In that scenario, answer accuracy remained broadly stable even as the systems became more dependent on synthetic sources.[4]
That is concerning precisely because the system can still look healthy at the surface.
The visible form of AI slop is easy to mock: generic articles, repetitive product descriptions and writing that sounds confident while saying very little.
The larger risk begins when low-quality generated material becomes evidence for another system.
At each step, qualifications can disappear, uncertainty can be smoothed over and a cautious statement can become a confident conclusion.
A highly capable model connected to an unreliable knowledge environment can produce unreliable decisions faster.
That is not transformation. It is accelerated confusion with better formatting.
The answer is not to treat anything created or approved by a person as inherently trustworthy.
Humans are mistaken, biased and perfectly capable of producing rubbish at scale. We managed that long before generative AI arrived.
The case for meaningful human involvement is not that people are always right.
It is that people introduce new observations, experiences and disagreements. We notice when circumstances change, decide which outcomes matter and remain accountable for the consequences.
Human review only adds value when the reviewer can see the underlying evidence, understands the stakes, has relevant knowledge and is genuinely able to reject the answer.
A hurried approval box adds theatre, not assurance.
AI may identify the fastest way to reduce customer service costs. Leadership must still decide whether the resulting experience is acceptable.
It may recommend automating a decision that affects access to a service. People must decide what evidence is sufficient, how exceptions are handled and who is responsible when the system gets it wrong.
The enduring human contribution is not producing every sentence manually.
It is connecting intelligence to evidence, purpose and accountability.
The answer is not automatically more AI or less AI. It is using AI without losing track of where information came from, what has been verified and who remains responsible for the result.
Original sources should remain accessible when AI-generated summaries, recommendations or documents enter an organisation’s systems. A confident summary is not a replacement for the policy, dataset, research paper, customer conversation or operational record beneath it.
Generated drafts should also be distinguishable from established organisational knowledge. An output should not quietly become authoritative simply because it has been stored in the right system or repeated by several assistants.
For important uses, organisations need to test more than whether the AI can produce an impressive answer. They need to test the surrounding workflow with representative information, real users and difficult exceptions.
Does the system retain its source links? Does it communicate uncertainty appropriately? Does it perform better than the current process? What happens when the information is incomplete, contradictory or wrong?
The level of review should match the consequence of failure. A meeting summary and a recommendation affecting someone’s eligibility for a service should not be treated in the same way.
Clear ownership matters too. Someone must be responsible for deciding which generated information can be relied upon, how changes are recorded and how errors are corrected across connected systems.
Finally, AI systems need feedback from what actually happened.
Did the recommendation improve the result? Did errors decline? Did customers understand the experience? Did the software work in production? Did the policy have its intended effect?
Reality needs a seat at the table.
These controls should not exist only in a governance document. They need to be reflected in source links, permissions, review points, version history, monitoring and decision rights.
The more important question is whether we preserve something outside the machine against which those things can be tested.
The future worth building is not one where humans manually write every sentence.
Nor is it one where machines create everything and then use their own output as evidence that they are correct.
It is one where AI expands what we can explore, while the connection between claims and evidence, and between decisions and accountability, remains intact.
More content is easy. Better knowledge is the work.
AI may not run out of content.
But it could run out of ground truth.
Author's Note
This article began with a question I asked AI. The conversation helped test the premise, challenge my assumptions and identify relevant research. The argument, editorial judgement and final responsibility are mine.
Sources and Further Reading
Silver, D. et al. “Mastering the Game of Go Without Human Knowledge.” Nature, 2017.
Shumailov, I. et al. “AI Models Collapse When Trained on Recursively Generated Data.” Nature, 2024.
Kazdan, J. et al. “Collapse or Thrive: Perils and Promises of Synthetic Data in a Self-Generating World.” Proceedings of the 42nd International Conference on Machine Learning, 2025.
Yu, H., Kim, D. and Kim, Y.-B. “Retrieval Collapses When AI Pollutes the Web.” Proceedings of the ACM Web Conference, 2026.

Cypha acknowledges Traditional Owners of Country throughout Australia and recognises the continuing connection to lands, waters and communities.
We pay our respect to Aboriginal and Torres Strait Islander cultures; and to Elders past and present.